A practical, simulation-based walkthrough of GraphEval, showing how knowledge graphs and NLI models can detect and localize hallucinations in LLM outputs.
<!– –>
# Introduction
Hallucinations remain one of the most persistent challenges in large language models (LLMs). They occur when a model generates content that is factually incorrect, nonsensical, or entirely fabricated—often because the model lacks reliable internal knowledge on the topic.
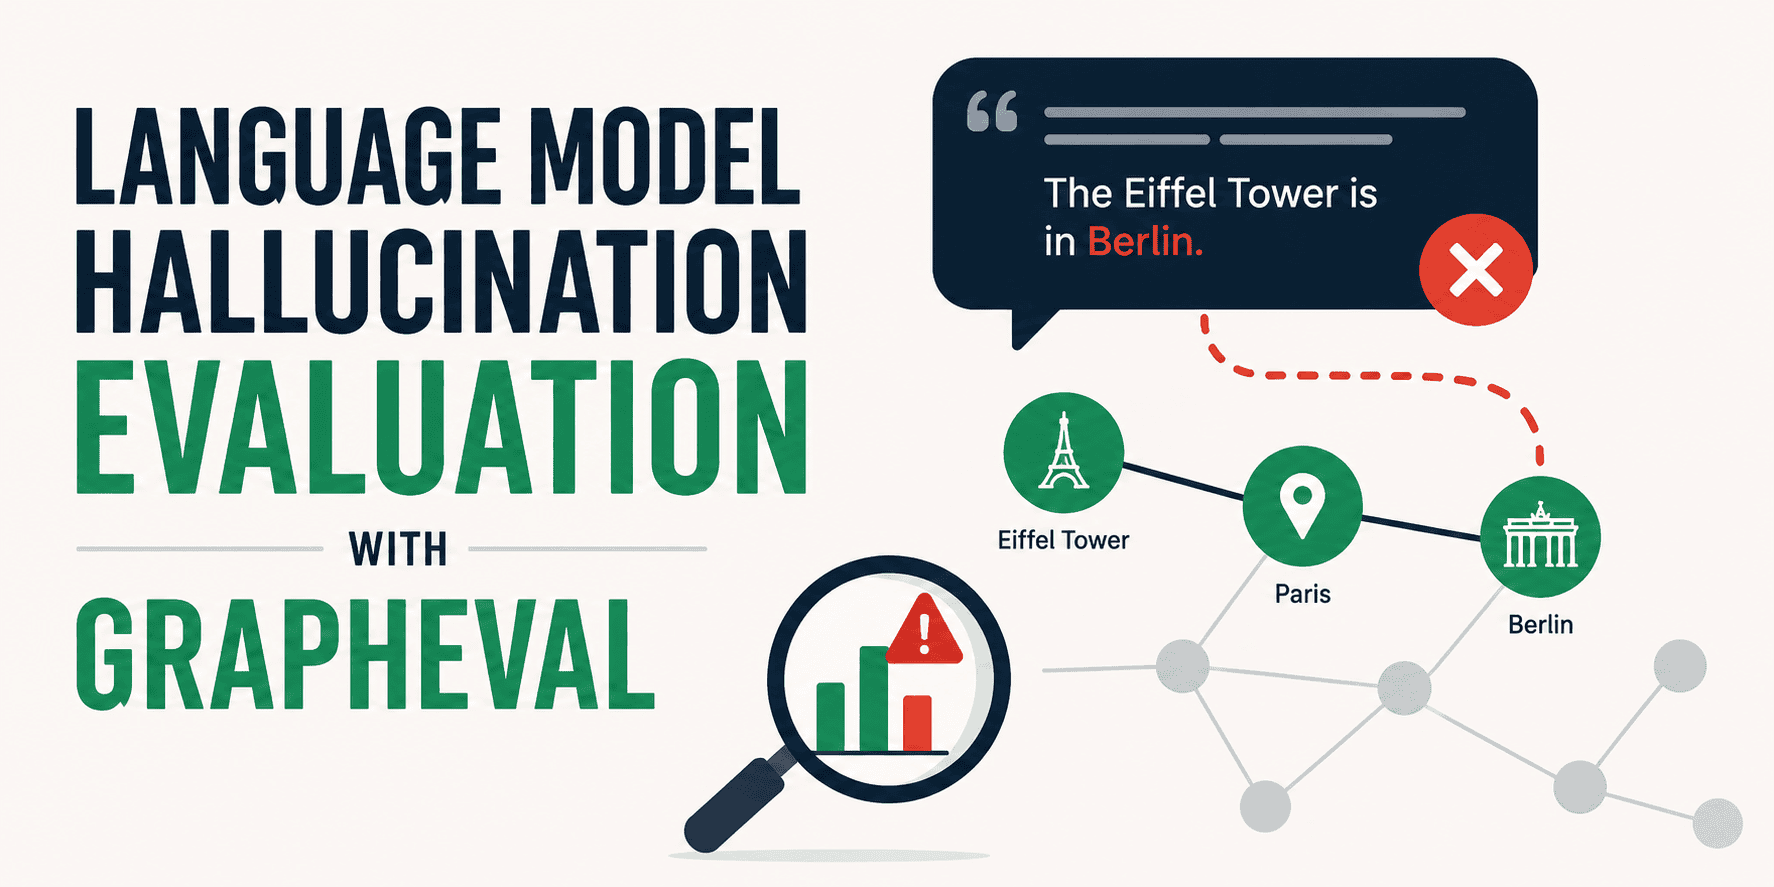
While many solutions have emerged to reduce hallucinations, fewer frameworks exist for systematically diagnosing them. A recent study by Amazon researchers proposes using knowledge graphs for this purpose. Their framework, GraphEval, turns LLM outputs into structured graphs and evaluates each component for factual consistency.
In this article, we take a practical, simulation-based approach to walk through GraphEval’s core ideas. A lightweight code example—easy to run on your own machine—will help demystify how the framework works.
# GraphEval in a Nutshell
GraphEval uses knowledge graphs to identify and flag hallucinations in LLM-generated text. Unlike traditional metrics that produce a single score for accuracy or certainty, GraphEval follows a two-stage, explainable evaluation process that pinpoints exactly where a hallucination occurs.
The process works in two stages:
- First, a knowledge graph is constructed from the model’s response. This graph contains semantic triples in the form (Subject, Relationship, Object), where subjects and objects become nodes, and relationships become edges.
- Second, each triple is evaluated against a source context (a ground-truth knowledge base) using a natural language inference (NLI) model. Any triple that the NLI model cannot confirm as entailed—because it is contradictory or neutral—is flagged as a hallucination.
# Illustrating GraphEval Through a Code Example
Before we start, make sure you have the necessary libraries installed:
!pip install -q transformers networkx matplotlib torchThe goal of this example is to show how GraphEval works conceptually. To keep things lightweight, we replace computationally heavy stages with simulated alternatives.
We simulate a ground-truth knowledge base (the context) that contains factual information. In a real deployment, this context would come from retrieving relevant documents, for instance, from the vector database of a retrieval-augmented generation (RAG) system. Here we define it directly as source_context.
# The ground-truth context provided to the LLM
source_context = (
    "GraphEval is a hallucination evaluation framework based on representing information "
    "in Knowledge Graph (KG) structures. It acts as a pre-processing step and utilizes "
    "out-of-the-box NLI models to detect factual inconsistencies."
)
Now, suppose the following is the LLM’s response to a prompt like “explain succinctly what GraphEval is.” To begin stage one of the evaluation, we would ask an auxiliary LLM to build a knowledge graph from this response. The response and the follow-up prompt are shown below:
# The generated response we want to evaluate (contains a hallucination)
llm_output = (
    "GraphEval is an evaluation framework that uses Knowledge Graphs. "
    "It requires a highly expensive, enterprise-level server farm to operate."
)

# Prompt template that would theoretically be passed to a local/free LLM (e.g. Mistral-7B)
KG_EXTRACTION_PROMPT = f"""
You are an expert information extractor. Extract the core information from the following text as a Knowledge Graph.
Return the output strictly as a Python list of tuples in the format: (Subject, Relationship, Object).

Text: {llm_output}
"""
To avoid the heavy computational load of running a massive LLM locally, we simulate the extracted triples:
# Simulated extraction to bypass the heavy computational load of running a massive LLM locally
extracted_triples = [
    ("GraphEval", "is", "evaluation framework"),
    ("GraphEval", "uses", "Knowledge Graphs"),
    ("GraphEval", "requires", "expensive enterprise server farm")
]

print("Extracted Triples:")
for t in extracted_triples:
    print(t)
Output:
Extracted Triples:
('GraphEval', 'is', 'evaluation framework')
('GraphEval', 'uses', 'Knowledge Graphs')
('GraphEval', 'requires', 'expensive enterprise server farm')
We deliberately added a hallucinated triple—GraphEval does not require an expensive server farm—so we can see how the NLI stage catches it.
Now for the real action: the NLI process. The code below uses a pre-trained NLI model from Hugging Face. The model is publicly available, so no access token is needed. It compares each triple against the ground-truth context and flags any triple that is not predicted as entailment.
from transformers import pipeline

# Loading the open-source NLI model
print("Loading DeBERTa NLI model...")
nli_evaluator = pipeline("text-classification", model="cross-encoder/nli-deberta-v3-small")

def evaluate_triple(context, triple):
    subject, relation, obj = triple
    hypothesis = f"{subject} {relation} {obj}"

    # Checking if the context entails the hypothesis
    result = nli_evaluator({"text": context, "text_pair": hypothesis})

    # NLI models normally output: 'entailment', 'neutral', or 'contradiction'
    label = result['label'].lower()

    # In GraphEval, anything other than 'entailment' is flagged as a hallucination
    is_hallucinated = label != 'entailment'

    return is_hallucinated, label, hypothesis

# Running the evaluation pipeline
evaluation_results = []

print("n--- GraphEval Results ---")
for t in extracted_triples:
    is_hallucinated, nli_label, hypothesis = evaluate_triple(source_context, t)
    evaluation_results.append((is_hallucinated, nli_label))

    status = "🚨 HALLUCINATION" if is_hallucinated else "✅ GROUNDED"
    print(f"{status} | Triple: {t} | NLI Output: {nli_label}")
Output:
--- GraphEval Results ---
✅ GROUNDED | Triple: ('GraphEval', 'is', 'evaluation framework') | NLI Output: entailment
✅ GROUNDED | Triple: ('GraphEval', 'uses', 'Knowledge Graphs') | NLI Output: entailment
🚨 HALLUCINATION | Triple: ('GraphEval', 'requires', 'expensive enterprise server farm') | NLI Output: neutral
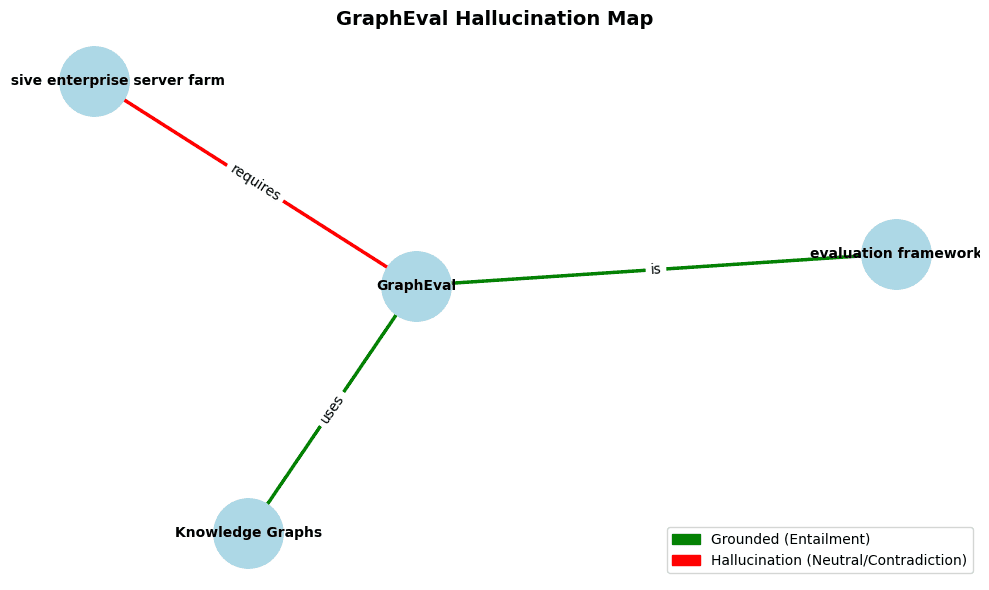
As expected, the third triple is flagged as a hallucination.
For a visual summary, we can render the knowledge graph alongside the detection results:
import networkx as nx
import matplotlib.pyplot as plt
import matplotlib.patches as mpatches

def visualize_grapheval(triples, eval_results):
    G = nx.DiGraph()
    edge_colors = []

    for (triple, res) in zip(triples, eval_results):
        sub, rel, obj = triple
        is_hallucinated = res[0]

        G.add_node(sub)
        G.add_node(obj)
        G.add_edge(sub, obj, label=rel)

        # Color-code the edges based on the NLI evaluation
        edge_colors.append('red' if is_hallucinated else 'green')

    # Set up the plot
    plt.figure(figsize=(10, 6))
    pos = nx.spring_layout(G, seed=42)

    # Draw nodes
    nx.draw_networkx_nodes(G, pos, node_color='lightblue', node_size=2500)
    nx.draw_networkx_labels(G, pos, font_size=10, font_weight='bold')

    # Draw edges and labels
    nx.draw_networkx_edges(G, pos, edge_color=edge_colors, width=2.5, arrowsize=20)
    edge_labels = nx.get_edge_attributes(G, 'label')
    nx.draw_networkx_edge_labels(G, pos, edge_labels=edge_labels, font_color='black')

    # Add legend
    green_patch = mpatches.Patch(color='green', label='Grounded (Entailment)')
    red_patch = mpatches.Patch(color='red', label='Hallucination (Neutral/Contradiction)')
    plt.legend(handles=[green_patch, red_patch], loc='lower right')

    plt.title("GraphEval Hallucination Map", fontsize=14, fontweight='bold')
    plt.axis('off')
    plt.tight_layout()
    plt.show()

# Render the knowledge graph
visualize_grapheval(extracted_triples, evaluation_results)
Resulting visualization:
# Closing Remarks
GraphEval offers a structured, explainable approach to detecting and localizing hallucinations in LLM outputs. By turning generated text into a knowledge graph and evaluating each triple with an NLI model, it pinpoints exactly where factual inconsistencies occur. This simulation shows how the core stages work and why the framework is valuable for production systems that need reliable hallucination detection.
Iván Palomares Carrascosa is a leader, writer, speaker, and adviser in AI, machine learning, deep learning & LLMs. He trains and guides others in harnessing AI in the real world.

Get the FREE ebook ‘KDnuggets Artificial Intelligence Pocket Dictionary’ along with the leading newsletter on Data Science, Machine Learning, AI & Analytics straight to your inbox.
By subscribing you accept KDnuggets Privacy Policy